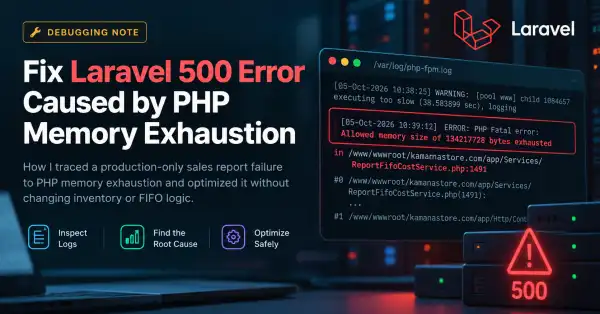
A Laravel application can work perfectly in development and still fail in production with a plain 500 Internal Server Error.
That was exactly the situation I ran into recently.
A sales report worked normally on my local environment, but the same page failed consistently in production:
GET /admin/sales-report

500 Internal Server Error
The difficult part was that Laravel’s application log did not contain the actual error.
That made the issue initially look like a possible regression in the report, inventory system, or FIFO calculation.
It wasn’t.
The real problem was PHP running out of memory while reconstructing a large amount of historical report data.
This debugging note explains how I traced it.
The Initial Situation
The report was responsible for calculating data such as:
- sales
- product quantities
- FIFO cost
- revenue
- gross profit
- inventory ownership
- variations
- current inventory balances
The application uses an inventory ledger where each stock movement records a running balance.
Current stock is determined from the latest applicable:
inventory_stocks.quantity_afterThe FIFO reporting system also needs historical purchase and sales movements to reconstruct product cost.
Everything worked locally.
Production returned a 500.
That difference was the first important clue.
Laravel Logs Didn't Show the Error
The normal place to start was:
tail -F storage/logs/laravel-YYYY-MM-DD.logI reproduced the problem several times.
Nothing related to the sales report appeared.
There were other unrelated application errors, but nothing explaining:
/admin/sales-reportAt this point, continuing to modify Laravel code based on assumptions would have been a mistake.
If Laravel doesn't log a fatal request, the failure may be happening at a lower level.
So I moved one layer down.
Check PHP-FPM and Nginx
The server was running PHP 8.3 through PHP-FPM.
I first inspected:
tail -n 100 /www/server/php/83/var/log/php-fpm.logThere were already warnings about slow PHP workers.
I then checked the website's Nginx error log:
tail -n 100 /www/wwwlogs/example.com.error.logThat finally exposed the real problem:
PHP Fatal error:
Allowed memory size of 134217728 bytes exhausted
And more importantly:
app/Services/ReportFifoCostService.phpThe request was explicitly:
GET /admin/sales-reportNow the problem was no longer speculative.
PHP had a memory limit of:
134217728 byteswhich is:
128 MBThe report exceeded it.
Why It Worked Locally
This is an important part of production debugging.
A bug does not have to reproduce locally to be real.
My local database contained substantially less historical data than production.
The report processed historical inventory movements, purchase layers, sales allocations and presentation data.
With a smaller dataset, memory consumption remained below the PHP limit.
Production had enough historical records to push the same algorithm past 128 MB.
So:
Local:       smaller dataset → HTTP 200
Production:  larger dataset  → memory exhausted → HTTP 500
The application logic did not suddenly behave differently.
Its memory usage simply scaled poorly.
The Real Memory Problem
The fatal line itself was not necessarily the source of the problem.
PHP reported memory exhaustion while creating report identities and cost slices, but by that point the service had already retained several large structures.
The report effectively had data similar to:
full inventory history
+ FIFO movement state
+ sale allocations
+ return slices
+ order details
+ report identities
+ presentation structures
This distinction matters.
When PHP reports:
Allowed memory size exhausted on line 736it only means that line requested the allocation that finally exceeded the limit.
It does not mean line 736 alone consumed 128 MB.
Don't Immediately Increase memory_limit
A common response would be:
memory_limit = 512MThat may make the error disappear temporarily.
But it doesn't fix the scaling problem.
As production data continues growing, the same report could eventually consume:
256 MB
512 MB
1 GB
...
Increasing memory can be useful as an emergency mitigation, but I wanted the report itself to use less memory.
Optimizing the Report Without Changing Business Logic
This part was especially important.
The report is connected to inventory and FIFO calculations, so performance optimization could not be allowed to alter business behavior.
Several invariants had to remain untouched.
Current Inventory
Current stock still comes from the latest:
quantity_afterfor the correct combination of:
inventory owner
product
normalized variation
It must never become:
SUM(quantity_after)because quantity_after represents a running balance.
For example:
100
99
98
97
means the current stock is:
97not:
394FIFO Must Stay FIFO
The report's costing logic also had to remain unchanged.
The optimization could not replace FIFO with:
average cost
latest purchase price
product purchase price
or any simplified approximation.
Historical cost layers still needed to be consumed in their proper FIFO sequence.
Performance work should change how efficiently the data is processed, not what the data means.
What I Optimized
Instead of rewriting the inventory system, I focused only on unnecessary memory retention inside the report.
1. Stream the Initial Ledger Data
The original flow created an additional full query-result collection before building the ledger index.
The optimized flow streams the rows directly into the required index.
That removes one large in-memory representation.
Conceptually:
// Expensive pattern
$rows = $query->get();

foreach ($rows as $row) {
    $index[$row->id] = $row;
}
became closer to:
foreach ($query->cursor() as $row) {
    $index[$row->id] = $row;
}
The exact implementation depends on the surrounding algorithm, but the principle is simple:
Don't keep two complete representations when only one is necessary.
2. Restrict Sibling Order Details
The report previously retained more historical order details than the selected report actually needed.
The optimized version loads sibling details only for orders represented by the financial report.
Importantly, this was not allowed to break returns.
A return inside the current reporting period can reference a sale that occurred before the report period.
That scenario was tested separately.
3. Retain Only Useful Historical Sale Slices
Historical movements still need to be replayed for FIFO.
But that does not necessarily mean every historical presentation structure has to remain in memory.
The optimized implementation retains historical sale slices only when they can actually be used by:
- a financial report line
- a return
FIFO replay still processes the necessary movement history.
The optimization reduces retained output structures rather than deleting required FIFO history.
4. Limit Presentation Identities
Another useful distinction was between:
data required to calculate the reportand:
data required to present the reportLedger reconciliation still runs across the necessary historical dataset.
But presentation identities only need to be created for relevant financial lines.
Avoiding presentation objects for unrelated historical identities reduced memory further.
The Memory Difference
I created a synthetic dataset locally to test how the report scaled.
With 10,000 unrelated inventory identities:
Before: ~78 MB peak
After:  ~50 MB peak
That is roughly a:
28 MB reductionMore importantly, at 20,000 identities under the same 128 MB PHP limit:
Original implementation:
memory exhausted

Optimized implementation:
completed at ~86.5 MB
That is the more meaningful result.
The goal was not simply to save a few megabytes.
The goal was to change the report from:
fails as data growsto:
continues processing with reasonable headroomProtecting Returns
One of the highest-risk optimizations involved historical sale slices.
Consider this case:
Original sale:
September

Customer return:
October

Report period:
October
If the optimization retained only October sales, the report could lose the FIFO cost associated with the September transaction.
So I added a focused regression test for exactly that scenario.
The return correctly resolved:
FIFO cost: ₹90.00with the expected original cost layers and no fabricated return layer.
The optimized result matched the original implementation.
Validation
After the optimization:
17 FIFO unit tests passed
95 assertions passed
I also ran:
php -l ...for PHP syntax validation and:
git diff --checkBoth passed.
Database-backed feature tests could not run in the local environment because the configured MySQL hostname was unavailable, so I did not treat local testing as final proof.
The real test was production.
Production Verification
After deployment, I opened:
/admin/sales-reportThe page loaded successfully.
No more:
Allowed memory size exhaustederrors appeared for the report.
More importantly, the optimization did not require changing:
quantity_after inventory semantics
FIFO costing
inventory ownership
product variation isolation
checkout stock deduction
The production issue was fixed at the layer where the problem actually existed: report memory consumption.
A Useful Debugging Lesson
There were a few useful reminders from this issue.
A 500 isn't always a Laravel exception
If nothing useful appears in:
storage/logs/laravel.logcheck:
PHP-FPM
Nginx
Apache
system logs
Laravel cannot log every failure if PHP itself terminates first.
Local success does not invalidate a production problem
Performance problems frequently depend on data volume.
100 records ≠ 100,000 recordsA report can be logically correct and still have poor scaling characteristics.
Protect business logic while optimizing
When performance code touches accounting, inventory or FIFO systems, the safest question is:
Can I reduce the amount of data retained without changing what the algorithm calculates?
That approach was much safer here than rewriting the costing logic.
Final Takeaway
The eventual fix was not:
increase PHP memoryand it was not:
rewrite FIFOIt was:
load less unnecessary data
retain fewer duplicate structures
separate calculation data from presentation data
preserve the existing business rules
When a production Laravel report starts failing as the database grows, inspect how much historical data is being materialized at once.
The query may be perfectly valid.
The calculation may also be perfectly valid.
Sometimes the real bug is simply that you're keeping far more of the result in memory than you actually need.